Ege Onur Taga

I am a Ph.D. student in Electrical and Computer Engineering at the University of Michigan, advised by Prof. Samet Oymak. I work on machine learning methods that are effective, data-efficient, and theoretically grounded.

My research interests lie at the confluence of:

  • foundation models for structured data (time series + tabular), and
  • large language models (post-training, test-time adaptation).

I received my B.S. in Computer Engineering from Boğaziçi University in Istanbul, where I double majored in Mathematics and graduated as valedictorian.

news

Evolutionary Feature Engineering for Structured Data was accepted to NeurIPS 2026. See you in Sydney!
Evolutionary Multi-Task Optimization for LLM-Guided Program Discovery is available as a preprint.
Happy to announce that I will be interning at IBM Research (T. J. Watson) as a Research Scientist this summer!
Learning to Correct: Calibrated Reinforcement Learning for Multi-Attempt Chain-of-Thought was accepted to ICML 2026.
Learning to Bet for Horizon-Aware Anytime-Valid Testing was accepted to ICML 2026.
FAF and Retrieval Augmented Time Series Forecasting were accepted to AISTATS 2026.
Happy to announce that I will be interning at Uber San Francisco as a PhD Software Engineer this summer!
Our knowledge-distillation paper was accepted to ICLR 2025 as a Spotlight.
TimePFN was accepted to AAAI 2025, and received a Spotlight at the NeurIPS TSALM Workshop.
Efficient Contextual LLM Cascades was accepted to NeurIPS 2024.

selected publications (full)

EFE Figure from Evolutionary Feature Engineering for Structured Data
NEURIPS 2026
Evolutionary Feature Engineering for Structured Data
Ege Onur Taga, Yilin Zhuang, M. Emrullah Ildiz, Petros Mol, Abhimanyu Das, Karthik Duraisamy, Samet Oymak
EMO Figure from Evolutionary Multi-Task Optimization for LLM-Guided Program Discovery
PREPRINT 2026
Evolutionary Multi-Task Optimization for LLM-Guided Program Discovery
Halil Alperen Gozeten, Xuechen Zhang, M. Emrullah Ildiz, Ege Onur Taga, Tara Javidi, Samet Oymak
CAL-GRPO Figure from Learning to Correct: Calibrated Reinforcement Learning for Multi-Attempt Chain-of-Thought
ICML 2026
Learning to Correct: Calibrated Reinforcement Learning for Multi-Attempt Chain-of-Thought
M. Emrullah Ildiz, Halil Alperen Gozeten, Ege Onur Taga, Samet Oymak
Learning to Bet Figure from Learning to Bet for Horizon-Aware Anytime-Valid Testing
ICML 2026
Learning to Bet for Horizon-Aware Anytime-Valid Testing
Ege Onur Taga, Samet Oymak, Shubhanshu Shekhar
Time2Decide Figure from Covariance-Aware Transformers for Quadratic Programming and Decision Making
COLM 2026
Covariance-Aware Transformers for Quadratic Programming and Decision Making
Kutay Tire, Yufan Zhang, Ege Onur Taga, Samet Oymak
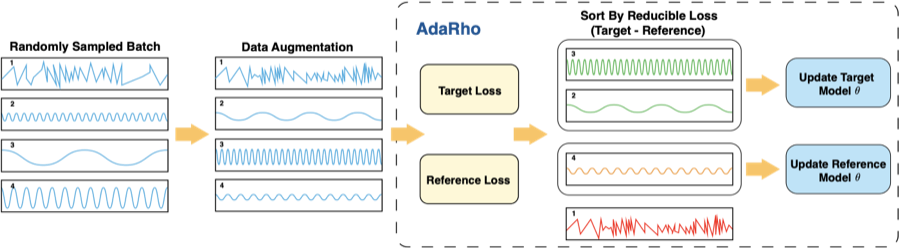
FAF FAF pipeline: a randomly sampled batch is augmented, then sorted by reducible loss between target and reference models to select which series update each model
AISTATS 2026
Filter, Augment, Forecast: Online Data Selection for Robust Time Series Forecasting
Ege Onur Taga, Halil Alperen Gozeten, Kutay Tire, Rahul Dalvi, Reinhard Heckel, Samet Oymak
Retrieval TSF Figure from Retrieval Augmented Time Series Forecasting
AISTATS 2026
Retrieval Augmented Time Series Forecasting
Kutay Tire*, Ege Onur Taga*, M. Emrullah Ildiz, Samet Oymak
* Equal contribution.
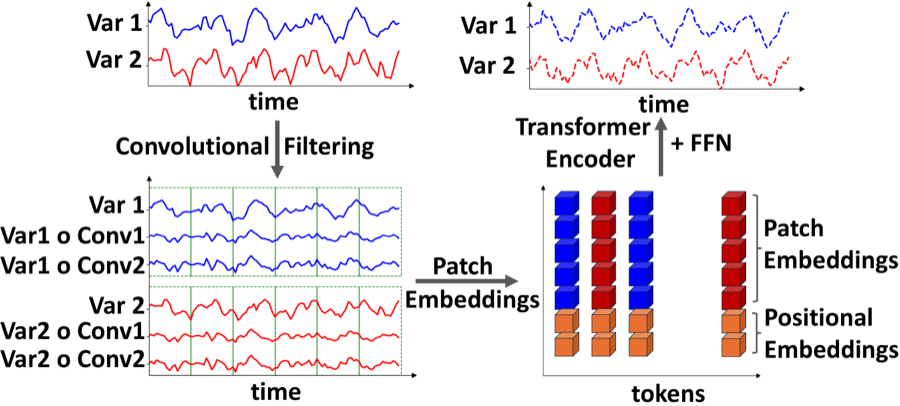
TimePFN TimePFN architecture: convolutional filtering of multivariate series into patch and positional embeddings, encoded by a transformer to produce forecasts
AAAI 2025
TimePFN: Effective Multivariate Time Series Forecasting with Synthetic Data
Ege Onur Taga, M. Emrullah Ildiz, Samet Oymak
Also appeared in NeurIPS TSALM Workshop as Spotlight.
Knowledge Distillation Figure from High-dimensional Analysis of Knowledge Distillation: Weak-to-Strong Generalization and Scaling Laws
ICLR 2025 SPOTLIGHT
High-dimensional Analysis of Knowledge Distillation: Weak-to-Strong Generalization and Scaling Laws
M. Emrullah Ildiz, Halil Alperen Gozeten, Ege Onur Taga, Marco Mondelli, Samet Oymak
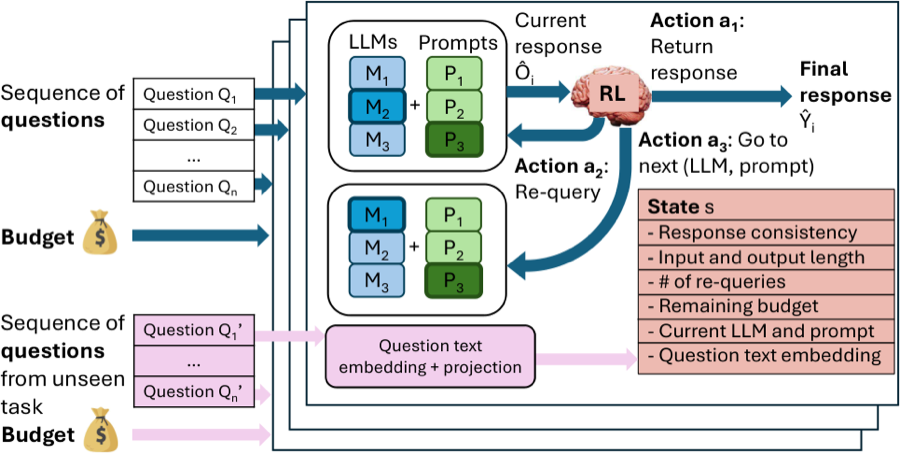
LLM Cascades Budget-constrained RL policy that routes questions through a cascade of LLMs and prompts, choosing to return, re-query, or escalate based on response consistency and remaining budget
NEURIPS 2024
Efficient Contextual LLM Cascades through Budget-Constrained Policy Learning
Xuechen Zhang, Zijian Huang, Ege Onur Taga, Carlee Joe-Wong, Samet Oymak, Jiasi Chen